- Arcade.dev says its Tool Recommendation feature cuts tool-description tokens by up to 91% in a model, while its full-workflow test shows a 7.6% cut in total token charges.
- The two figures use different denominators, and none has been independently verified. Buyers should match the number to their own agents.
- Before adopting, count the tools each agent uses, check where large tool results are stored, and price the platform fees too.
Every agent re-reads a menu
An AI agent that works inside business software must first know what it can do. Each action, such as searching an inbox or updating a ticket, comes with a written description. The model reads those descriptions as tokens, the unit AI vendors bill by.
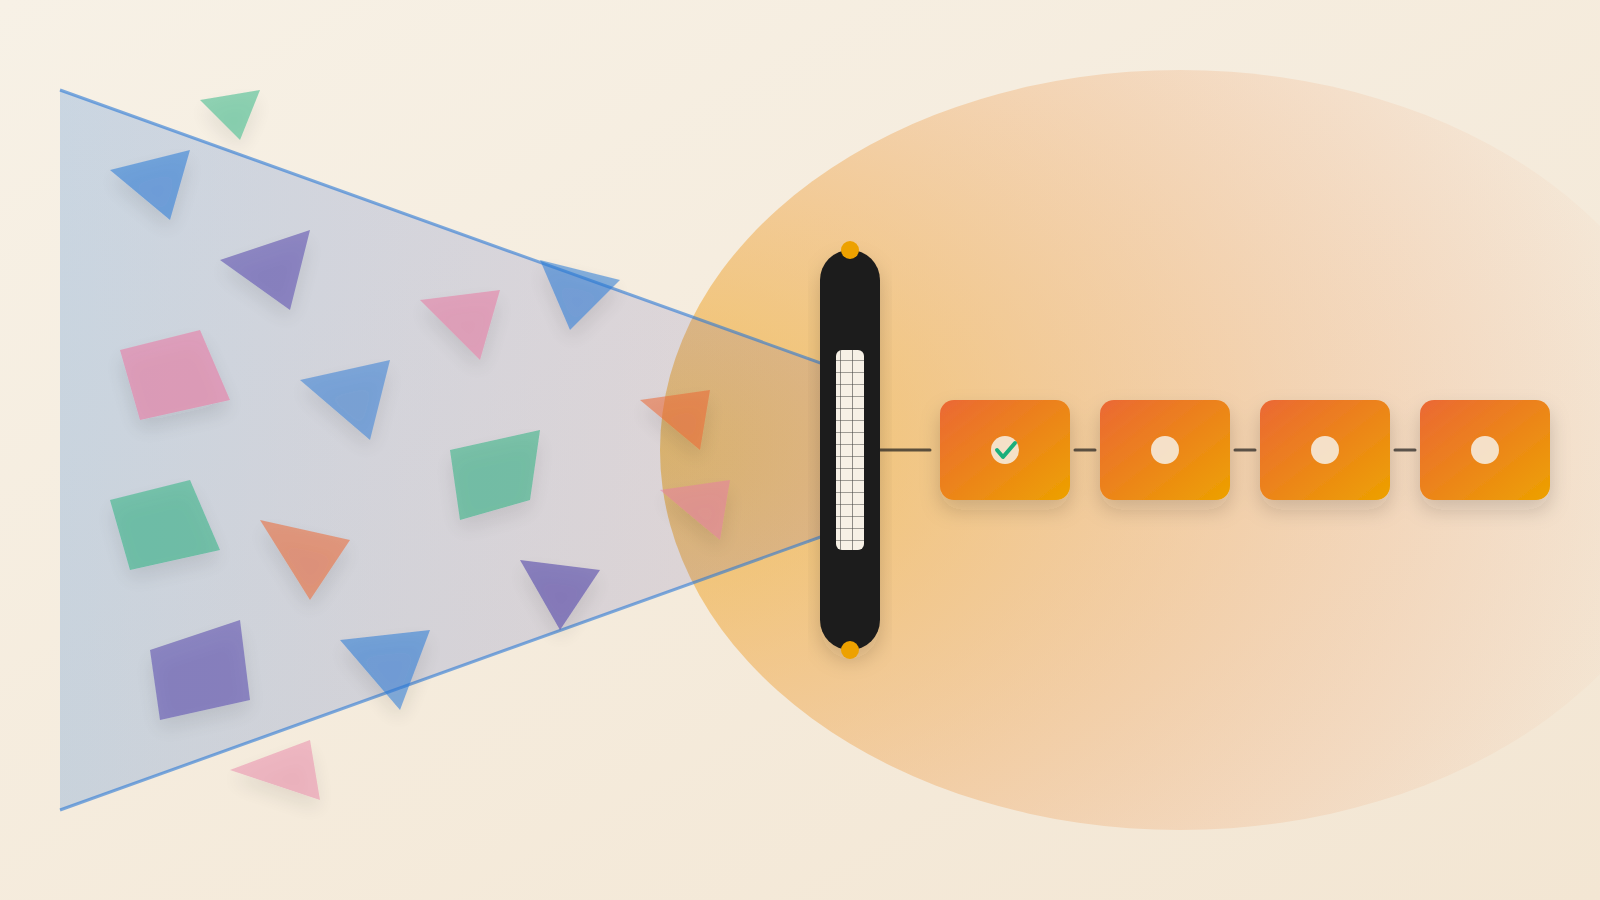
Arcade.dev, a startup that lets agents act in workplace systems under permission controls, says its catalog exceeds 8,000 tools. Putting that whole inventory in front of a model would cost around 1.75 million tokens of reading, ahead of any request.
This points to a cost that is easy to miss. Connecting an agent to more systems makes every conversation heavier, because the agent pays to read its menu of options. The reach of an agent is billed in reading.
How Tool Recommendation works
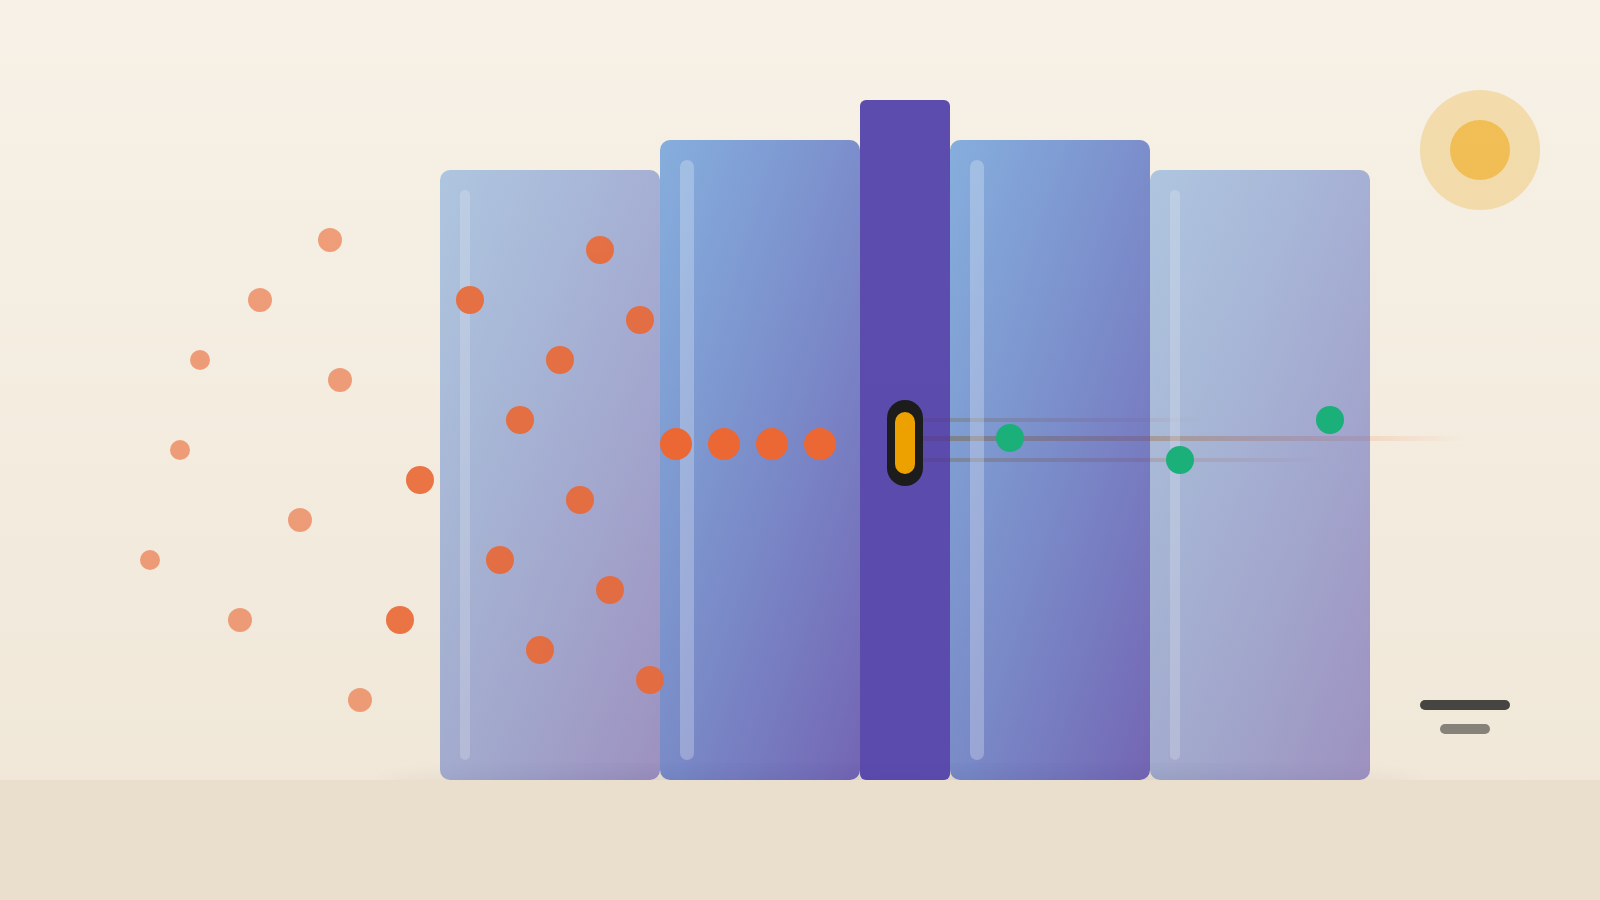
Arcade's new feature replaces the full menu with a few entry points. The agent describes what it needs. Arcade searches and ranks its catalog with smaller, specialized models and returns a shortlist. It then runs the action the agent picks.
The agent's own model, such as Claude or ChatGPT, still makes the final choice. The feature works through MCP, a common way to connect assistants to outside applications. It is switched on at Arcade's gateway. Arcade Cloud customers get it from October 15 with no separate feature charge, but normal platform fees still apply.
One product, several denominators
Arcade reports several savings figures. Each measures something different.
For Claude Opus 5, that model shows tokens falling from 411,729 to 38,170. Arcade says plainly: "These are definition-token savings, not whole-session savings."
For a typical interaction of three requests, Arcade estimates about 20%. If large tool results stay in the conversation, it estimates only 5% to 7%.
The broadest test ran 64 workflows across 408 sessions with Codex and Claude Code. It compared runs with and without discovery.
Broken out by agent, the test found a 9.7% reduction with Claude Code and 5.5% with Codex. The Codex range of results reaches down to zero, so that gain may be nothing at all. VentureBeat has not reproduced the tests.
The lesson here is simple. A savings figure is only as useful as its denominator. The 91% describes one slice of the bill in a model, and the 7.6% is a measured result across more of it. Neither is a forecast of your invoice.
The layer that saves also decides
Discovery on demand is not unique to Arcade. VentureBeat notes that Microsoft's Foundry Toolboxes and Anthropic's Tool Search Tool defer loading tool definitions. OpenAI's Responses API supports deferred functions from GPT-5.4. Anthropic cites an 85% reduction from its own example, but it measured against a different starting point than Arcade did.
Arcade's pitch is to bundle discovery with execution controls. It says the layer checks both the user's rights and the agent's permitted actions. It adds that login credentials stay out of what the model sees, rules can run before and after each action, and audit records flow out through OpenTelemetry.
That bundle is useful, and it also concentrates trust. One layer now decides which actions an agent sees, which it can run and what gets logged. It deserves the same review as any system that holds credentials and sets policy.
Not every agent needs it
By Arcade's own modeling, an agent with fewer than about 25 to 28 tools is better served by a plain fixed list. Co-founder Sam Partee acknowledged that repeated recommendation calls could erase the savings or raise costs. He did not give verifiable figures on how often that happens.
Arcade also compared its tool retrieval with Microsoft Foundry on a public benchmark. The runs used different settings, and Arcade calls the result a potential advantage, not a controlled head-to-head. Retrieval scores do not measure whether a business task gets finished.
Cost is not only tokens. On one paid tier, Arcade lists usage prices of ten cents per authorization event and one cent per tool call. No named customer's complete before-and-after spending has been shared.
Questions to put to your team
How many tools does each of our agents actually use? If it is under roughly 25 to 28, a fixed list may cost less.
Which denominator is the vendor quoting: definitions only, input only, or the full bill?
Do our large tool results stay in the conversation? Arcade's modeled savings fall to 5% to 7% when they do.
What do platform and per-action fees add, and who reviews the audit records?
Ask for the number that matches your own workflow. The headline figure belongs to someone else's.
Produced by the WebPulse Newsroom with AI assistance from the original reporting credited below, and checked against that source by our editorial review. How we use AI.
Original reporting: VentureBeat.