- Bridgewater's Aaron Linsky said a simple permissioned search seemed fine at first, then failed as the firm added documents to its private research library.
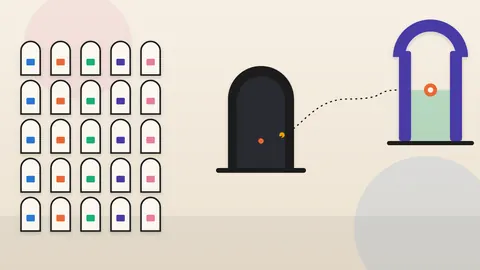
- The public web has one audience, so any page can go to an AI analyst. Private company data has a different permission set on each document.
Bridgewater Associates, an investment firm, is putting machines at the centre of its research. On the AI Engineer show, Aaron Linsky, its head of product engineering, and Nikhil Benesch, CTO of search company turbopuffer, treated permissions as the problem that broke the firm's first search setup. Each document may have a different list of people allowed to read it.
What was said
A speaker on the show started with a contrast. The public web is public, so every document can go to the AI analyst, whoever asks. Inside a company, that breaks down. In the speaker's words, "Every email, every meeting note, every report might have a completely different set of permissions attached to it". The speaker called this a classically hard problem in information retrieval.
Linsky described Bridgewater's Vault, an index of about 100 million documents. They include the firm's own writing and meeting recordings, plus 135 outside sources. He said those sources carry permissions, so a document may not be open to everyone at the firm. Human investors and AI agents both read from the Vault.
Linsky said the first version, built without turbopuffer, seemed fine. Then the firm added more documents and it failed badly. The excerpts do not say whether it became slow or inaccurate.
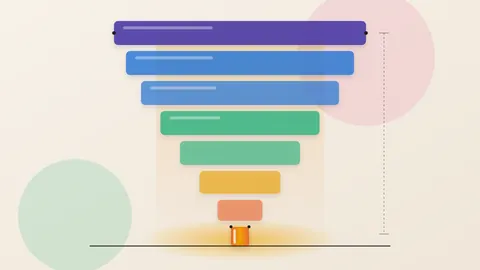
The show notes explain the trade-off. A search by meaning must return only documents the asker may see. Filtering after the search can leave too few good results. A speaker said that way, "you don't turn it up. So you have very poor recall." Recall means how many of the right documents the search finds. Filtering before the search, the notes say, is too slow. Turbopuffer says its "native filtering" over a clustered index combines both. The notes claim about 120 milliseconds for nine in ten searches across 400 million vectors.
Why it matters
Our reading: the speakers did not say model quality is unimportant. But their example suggests the hard engineering for research agents is retrieval that respects who is asking. The public web never had to do this.
Managers who buy or build AI research tools should ask a specific question. How does the system apply each user's access rights during search, and was it tested at full size? A small demo can look fine and still fail at scale, as Bridgewater's first setup did.
The other side
This is one firm's account, told alongside a vendor that sells the fix. The speed and recall figures come from the show notes, and the excerpts include no independent test. They also stop before explaining how native filtering works, so we cannot judge the claim.
Linsky said his permissions diagram was heavily simplified. Real access rules are likely messier than the example he showed. The idea that permissions matter more than smarter models is our argument, not something either speaker stated.
Written by the WebPulse Newsroom with AI assistance, and checked by our editorial review: every quotation was verified against the recording's transcript. How we use AI.
The conversation this talking point comes from
- AI Engineer: Can Your AI Analyst Keep a Secret? - Aaron Linsky, Bridgewater & Nikhil Benesch, turbopuffer (2026-10-25)