- Endor Labs argues that coding agents can take risky actions, such as installing packages, before any code reaches review, so scanning only the output leaves a gap.
- The vendor says teams should limit what agents can do and also check what they produce independently.
- Leaders should ask which agents run, what they can reach, and whether packages are checked at the moment of install.
Who is watching each step?
Picture the path a change takes to production: a request, generated code, an installed library, tests, a review, a merge. Endor Labs, a software security vendor, argues that a person once stood at each of those points. With coding agents, it says, a person often stands at only one.
That is the idea worth taking from the company's guide to the secure agentic development lifecycle, or ADLC. The risk is not only flawed code. It is that many of the steps behind the code now go unwatched.
Why Endor Labs says the old review ratio breaks
The guide leans on adoption data. In the 2026 Stack Overflow Developer Survey, 73% of respondents said they use coding assistants and agents daily, according to Endor Labs. Jellyfish studied 20 million pull requests from 200,000 engineers. It reports that AI help now produces most of the code at 64% of companies.
Agents that open a pull request from start to finish are only a small share of that data, Endor Labs says. It describes that share as growing fast. Its argument about review rests on that growth, not on how common such agents are today.
The difference is who acts. An assistant proposes a line and a person decides. An agent works through the repository itself. It reads files, changes many of them, installs libraries, runs tests and submits the result. If one agent submits dozens of changes a day, Endor Labs argues, a rule of one reviewer per change cannot keep up.
The guide also cites Faros AI telemetry, which shows pull requests merged with no review at all are up 31.3%. Endor Labs calls that a correlation, not proven causation.
What happens before a diff exists
A code scanner reads a diff, which is the list of lines that changed. Agents act earlier than that. Endor Labs describes a long list of things an agent may do while finishing one task: run commands in a shell, launch scripts, add packages, change settings and call tools outside the repository. In its account, the agent usually works with the developer's own repositories, cloud credentials and tokens.
Those actions happen while the agent works, using the developer's own access. A scanner that reads the finished pull request sees only what was committed. A malicious package installed along the way, or a secrets file read along the way, may leave nothing in the diff.
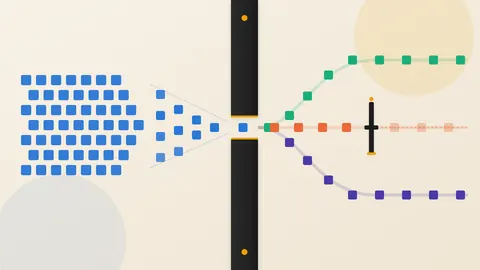
Endor Labs' answer for installs is a package firewall. It checks each package when the agent runs the install command. It blocks risky ones before they arrive, including known malware and names that look hallucinated or typosquatted. The guide places this check ahead of the pull request.
The dependency problem, with limits on the data
The guide cites Endor Labs' own State of Dependency Management research. It found that only one in five AI-recommended dependency versions is safe. The research also reported that 49% carry known vulnerabilities and that 34% are hallucinated, meaning the package does not exist. These are separate figures and are not shares of one whole.
Read those figures with care. They come from the vendor's research, and the guide does not give the sample or the models tested. They describe versions that AI recommended, not every install an agent performs.
The risk is easy to see, though. An attacker can register a name an agent is likely to invent, then wait for installs. The guide offers an illustrative scenario, not a reported incident. Say an agent is building a reporting feature and decides, midway, that it needs a parsing library. It runs the install command. The name it chose is not yet on the registry, and someone registered a near match a week earlier. Endor Labs uses the case to show where an install-time check would step in.
The same research looked at MCP servers. An MCP server is a connector that gives an agent access to outside tools and data. Endor Labs reports that individuals built 75% of them and 82% use sensitive APIs. It adds that an unvetted server sits inside the agent's trust boundary, with the agent's permissions.
Two layers, because one is not enough
The guide's core rule has two halves: limit what agents can do, and check independently what they produce. Each half alone leaves a hole, Endor Labs says.
Think of a new contractor. You limit which rooms they can enter on day one. You also inspect the finished work. Inspection alone misses what they did while inside the building. Locked doors alone say nothing about whether the wiring they installed is sound.
Endor Labs gives two examples. A malicious package can be installed without appearing in a diff. A sandboxed agent can still write an endpoint with no authentication.
One 2026 benchmark, which the guide does not name, found that 61% of SWE-Agent solutions using Claude 4 Sonnet worked correctly. Only 10.5% were secure. That is a result on a test set, not a measure of real deployments.
Developers seem to sense the gap. The guide cites the Stack Overflow survey: 48% of respondents trust AI output only when verifying it is easy. A further 16% extend trust for most tasks, stopping short of important decisions.
What to ask your team
One caution first. Endor Labs sells products for these controls. Its figures come from its own research or from studies it cites. Treat the guide as a vendor's map, not an audit. The company also describes its lifecycle stages as a working model rather than an official standard.
The questions hold up on their own. Which agents run in your company, who launches them, and which tools and MCP servers do they reach? Endor Labs says you cannot secure activity you cannot see. Are packages checked when an agent installs them, or only after a pull request exists? Do agents use a developer's full credentials, or a narrower set? Does review of agent-written code look for design flaws, such as a missing permission check, or only known bad patterns? Endor Labs cites its own research finding that design flaws of this kind tend to get past static analysis, since each line of code looks fine on its own.
The lesson here is that review was about more than reading code. It meant a person at each step. As agents take over steps, each one needs a control of its own.
Produced by the WebPulse Newsroom with AI assistance from the original reporting credited below, and checked against that source by our editorial review. How we use AI.
Original reporting: Endor Labs.