- Accuracy gives partial credit, so an agent that gets four of six checks right still scores 67 percent.
- Ryan Stevens of Ramp said all-or-nothing scoring "might be" the right measure for accounting, because an accountant who cannot trust each step may not use the agent.
A score that rewards partial success can make an AI agent look better than it is. Ryan Stevens, who leads applied science at Ramp, made this point on the AI Engineer show. He was describing how Ramp tests Stack, its AI agent for bookkeepers. In work where mistakes are costly, he suggested, the stricter test may be the one to optimize.
What was said
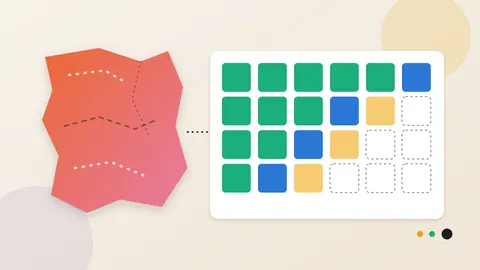
Stevens described two ways of scoring an agent. The first is accuracy. He gave an example task with six criteria. If the agent gets four right, it scores 67%, because partial credit counts.
The second is pass@k. Here the agent runs the same task several times. In his example, it got four right, then five, then all six on the third try. Stevens called this an all-or-nothing metric. The agent only passes on the run where everything is right. So pass@1 and pass@2 are zero, and pass@3 is one.
He suggested that in fields where mistakes carry a heavy price, with accounting as his example, this strict score could be the one a team aims at. His reason was about people, not maths. As he put it, "If an accountant can't trust that one of the steps is wrong, then they may not use your agent."
Stevens also said Ramp's results show high accuracy but very low pass@1 on its tests. He took that as a sign the tests are not yet saturated, meaning the models have not maxed them out. He added that when Ramp looked at why agents fail, accounting failures were mostly reasoning failures. The agent had the right data but reasoned through it incorrectly.
Why it matters
Our reading is that a headline accuracy figure tells a buyer less than it seems to. An agent that is right on most steps can still leave a bookkeeper checking everything. If each step must be re-checked, the time saved shrinks. The person who signs the books carries the risk, so they decide whether the tool is used at all.
For leaders buying or building agents, the question changes. Ask how often a task is finished with every step right, not how many steps are right on average. Ask also how the vendor tests this. Ramp's own approach, as Stevens described it, was to build test businesses with full books and run agents against the same data again and again.
The other side
Pass@k is one lens, and Stevens did not claim it is the only one. He showed accuracy alongside it. He also said pass@k "might be" the thing to optimize in accounting, which is a hedge rather than a rule.
His example also shows a limit. In it, the agent reaches a pass only on the third try. That tells us a retry can eventually succeed. It does not tell us whether an accountant would know which run to trust. The excerpt does not answer that.
The talk also leaves open how much trust a score can build. Stevens said the models are not that smart yet, and that Ramp had to spend four to six months building its tests. That is a real cost, and smaller firms may not be able to repeat it.
Written by the WebPulse Newsroom with AI assistance, and checked by our editorial review: every quotation was verified against the recording's transcript. How we use AI.
The conversation this talking point comes from
- AI Engineer: How Ramp Tests Its AI Bookkeeping Agent Before Customers Do - Ryan Stevens, Ramp (2026-11-08)