- A 2022 research technique, ROME, can change one fact stored in a language model by editing a few weights. Security vendor Stealthium says this can be done in memory, leaving files unchanged.
- Stealthium argues that tools built to watch files, processes and networks have little to see. Its detection claims come from the vendor itself.
- Leaders should ask whether anyone checks what their production models say, not only what files they load.
Much security tooling is built to watch for changes to something: a file, a process, a network connection. A model that has been quietly taught one wrong fact may show none of these. The lesson is that for AI systems, integrity has to mean more than an unchanged file. It has to include whether the answers are still the answers you approved.
What the research showed
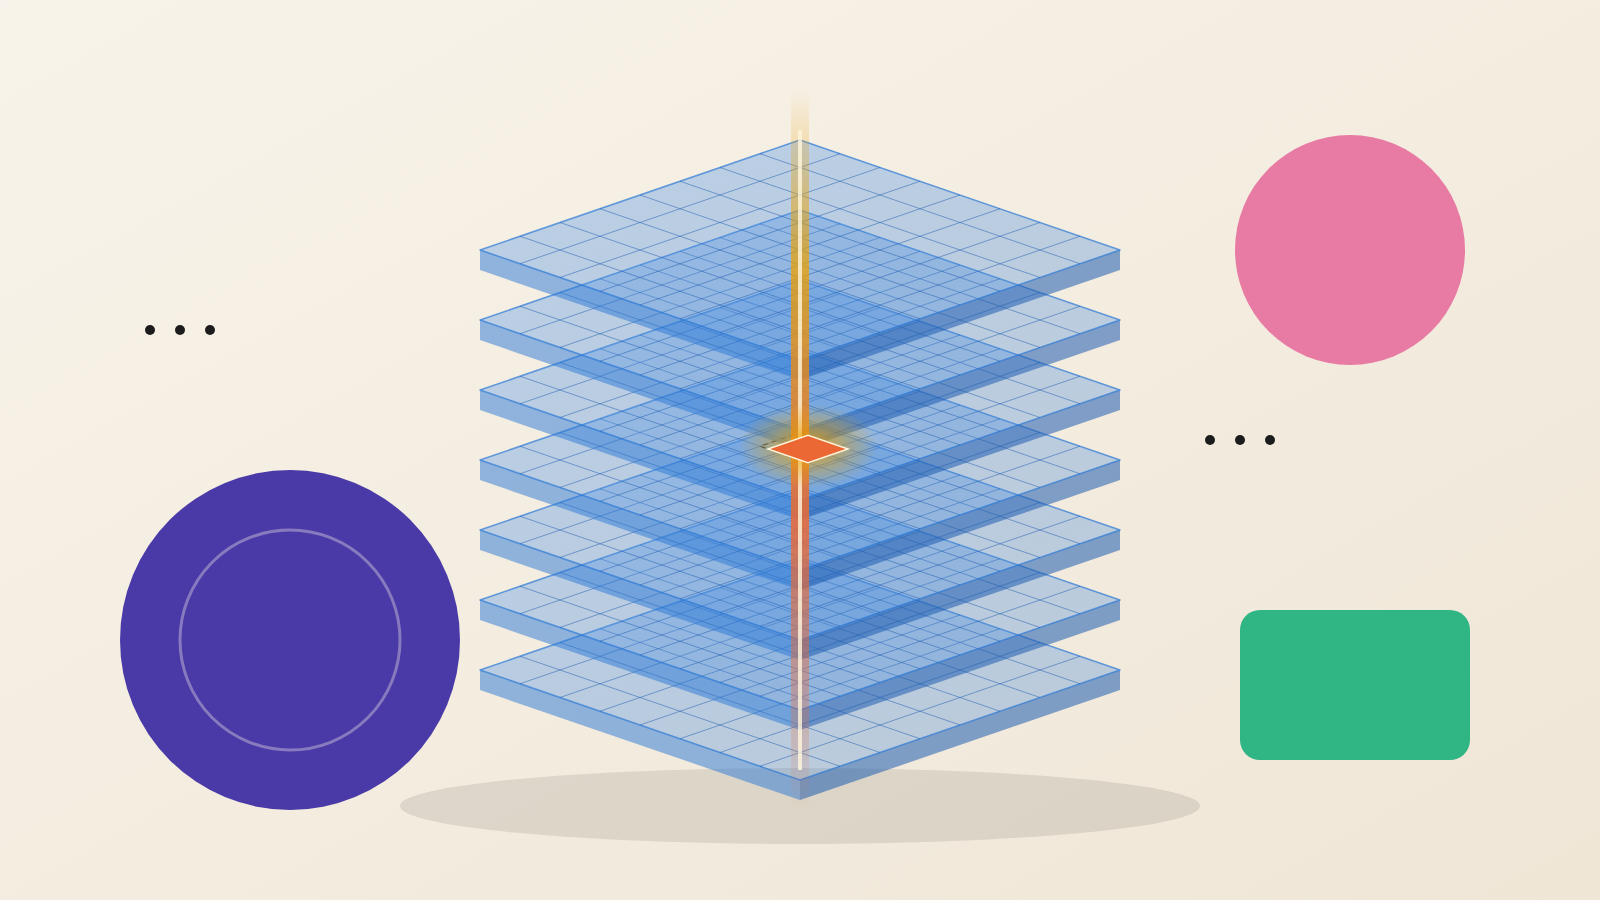
In 2022, researchers K. Meng, D. Bau, A. Andonian and Y. Belinkov published a paper at NeurIPS on how language models store facts. They found that factual associations correspond to "localized, directly-editable computations". The relevant steps sit in middle-layer feed-forward modules, which are internal blocks of the model that process each subject the model reads.
The team then built a method called Rank-One Model Editing, or ROME. It changes the weights of those modules to update one specific fact. The weights are the numbers that make up the model.
The researchers tested ROME on a standard editing task and on a new dataset of counterfactual statements. They report that it kept both specificity and generalization, while other methods gave up one or the other. In plain terms, the edit changed the target fact and left most other behavior alone.
The paper is about understanding and editing models. It does not describe an attack. The authors say direct manipulation of a model's inner workings "may be a feasible approach for model editing".
How Stealthium turns it into an attack
Stealthium, a security vendor, published a post on October 19 that treats ROME as an attack technique. It describes a malicious Python module that rewrites a model's weights in GPU memory, the memory of the chips that run AI workloads. According to Stealthium, the model can then be corrupted on a specific topic "without a single byte on disk changing". It says Mithril Security's PoisonGPT used the same technique.
Stealthium's point is that, to everything watching the machine, the tampered model still looks like "a model doing model things". A plain-English version: change a few of the numbers and you change what the model says.
How malicious code gets in
Stealthium notes that much GPU work runs under a Python interpreter, and Python has several ways to run code before anyone reviews it. The post gives four examples.
First, importing a package runs its setup code. Stealthium points to the April 2026 compromise of the lightning package on PyPI, tracked as CVE-2026-44484. In its account, the affected releases, 2.6.2 and 2.6.3, began running a credential-stealing program the moment someone imported the package.
Second, a startup file can run before the application does. The post says the March 2026 LiteLLM compromise used this route.
Third, model files can carry code. The post says researchers have found files on Hugging Face that, once loaded, gave an attacker a remote shell or contacted an outside server. It adds that the safetensors format avoids this, but many models still ship as pickles.
Fourth, text strings can become running code. Stealthium describes a Sysdig investigation of an Open WebUI plugin. The plugin buried its payload under 64 rounds of encoding, then executed it directly in memory, so nothing reached disk.
These are routes for getting code in. ROME is one thing such code could then do.
Why the usual tools see little
Stealthium argues that endpoint and application security tools watch process activity: files opened, child processes started, network traffic. A weight edit in GPU memory involves none of these. From the host, the post says, an AI job can look like "the same python3 process using a GPU".
The vendor says its runtime sensor links each CUDA kernel launch, a unit of work sent to the GPU, to the Python code that issued it. It also says it is researching a way to catch changes to the weights and trace them to the call stack, the chain of code calls behind the change.
These are the vendor's own claims. The text available to WebPulse ends before Stealthium's lab results, so we cannot assess how well its detection works. The post also does not tell us how common such attacks are.
What to ask your team
Start with where models run. Which production systems load models, and from which sources and file formats? Are pickle files still in use?
Then ask what is checked after loading. Does anyone test a fixed set of questions against the live model, so a changed answer on one topic gets noticed? Is there a record of which code touched the model's weights?
Finally, ask whether the Python packages around your AI jobs are pinned and reviewed. The entry points in this story are ordinary software supply chain problems.
A signed file proves what was shipped. It does not prove what the model is saying today.
Produced by the WebPulse Newsroom with AI assistance from the original reporting credited below, and checked against that source by our editorial review. How we use AI.
Original reporting: K. Meng, D. Bau, A. Andonian, Y. Belinkov (NeurIPS 2022).