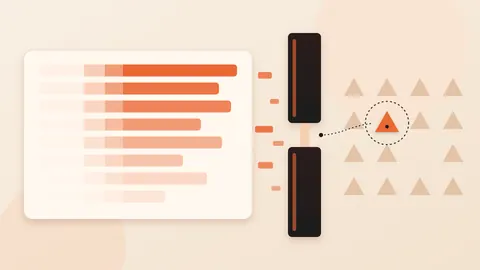
- Ant Digital Technologies says its LingDT-Decision-1.0 model used over 90% fewer tokens than large language models in its own tests. The results are not independently verified.
- Many business AI steps end in a label, score or routing choice, so paying for written text there may be wasted spend.
- Inventory those steps, measure their token cost, and test any decision model on your own data before relying on vendor figures.
Ant Digital Technologies describes a common pattern in business AI. A large language model writes out text. Then separate software parses that text into a decision. Picture a model that writes a whole paragraph so a program can pull out one word, such as "refund" or "urgent". The paragraph is not needed after that. This scene is our illustration, not a finding. If the pattern holds, the company paid for prose that nobody needed.
Ant says it is targeting this gap with a new model. The argument for leaders is simple: when a machine reads the output, text adds cost and no value. Much of the routine work inside AI agents may be choosing, not writing.
What Ant released
Ant Digital Technologies is the enterprise technology arm of Ant Group. Pandaily reports that it has released LingDT-Decision-1.0. The model comes in two sizes, 4B and 27B parameters. Parameters are the internal settings a model learns. More of them usually means a larger and costlier model.
The model runs on the company's DTMaaS platform. Ant has opened a time-limited free trial for developers there. It describes the model as built for structured business decisions, not open-ended text.
How a decision model differs
Ant's example is a customer message saying a parcel is still waiting to ship after three days. Software must sort it. Is it a refund request, a chase-up or a complaint? How urgent is it? Which team should take it? Does a person need to step in?
Ant says a general language model usually works through this token by token. Tokens are the small chunks of text a model reads and writes. The model writes out an answer, and separate software then turns that text into a decision. Ant says this chain is long, costly and more prone to error.
A decision model skips the writing. It judges directly within a defined set of options. Ant points to the frequent small steps inside AI agents: working out what a user wants, picking a tool, applying rules and assigning scores.
Ant also claims a first. Its model natively handles choosing several options at once, and decisions that run in sequence along a directed acyclic graph, or DAG. A DAG is a map of steps in which each step leads forward and nothing loops back. That shape fits many business processes, such as approval flows.
What the numbers do and do not show
Ant reports that in its tests on customer service, risk control and financial tasks, the model used more than 90% fewer tokens than large language models on the same tasks. Ant adds that answers came back as much as ten times sooner, with better results.
Ant also ran 23 open-source benchmarks. It says LingDT-Decision-1.0 scored above rival decision models, naming Microsoft-Decision-1 and Jev 1.13. Among models of similar size, Ant says its 27B version ranked first on accuracy.
These results are Ant's own. Pandaily notes they have not been independently verified. The report does not say which general language models were the comparison. Nor does it say how the tests were set up. Treat the figures as a claim to test, not a benchmark to plan around.
The lesson: match the tool to the job
Asking a model that writes essays to tick a box is like hiring a novelist to fill in a form. It works, but you pay for skill you do not use. The lesson here is that cost and reliability may depend on where a company places its language models, not only on which model it buys.
Pandaily reports that the release does not replace general language models. The model is meant to sit alongside them. The decision model takes the many routine choices. Large models are then free for reasoning and writing that has no fixed answer.
One caution applies. A model that picks from a fixed list is limited by the list. If a customer's problem fits none of the options, the system still has to route it somewhere.
Questions to put to your team
Start with an inventory. Which steps in your AI workflows end with a label, a score or a routing choice? For each, ask what happens to the language model's written output after it is generated.
Then ask for the numbers. How many tokens do those steps use today? How often does the parsing step fail? What happens to a ticket when it does?
If a team wants to test a decision model, set the terms first. Use your own data, not the vendor's. Measure cost, speed and accuracy against your current setup. Check that the options list covers the cases your staff actually see, including the ones that need a person.
The model that writes best is not necessarily the one that answers best. Sometimes the cheapest improvement is to stop paying for sentences.
Produced by the WebPulse Newsroom with AI assistance from the original reporting credited below, and checked against that source by our editorial review. How we use AI.
Original reporting: Pandaily.